Interpretable and explainable medical AI
We study how a model’s image evidence can be exposed, interpreted, and evaluated alongside its predictions.
What does an explanation reveal about a model, and how can that explanation be tested?
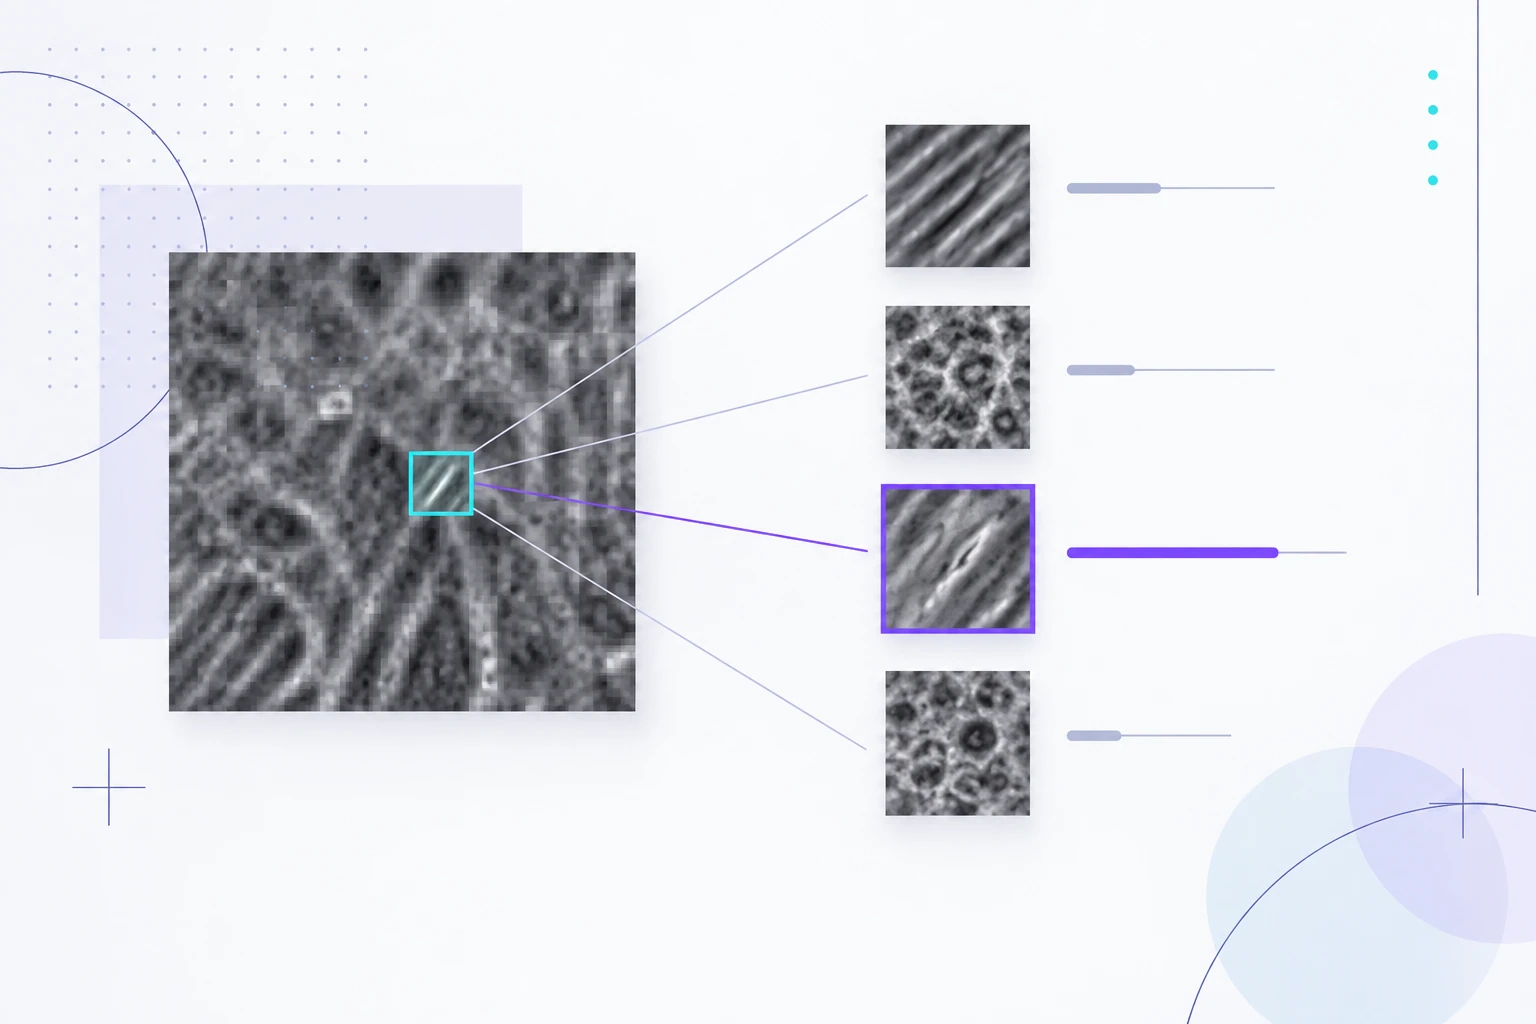
Method overview
Exposing and evaluating image evidence
A region or feature representation is associated with the model’s output.
Schematic of the research approach; image patterns and measurements are illustrative.
Research overview
An accurate prediction does not automatically tell a reader which evidence a model used. Our research examines interpretable architectures and methods for explaining medical image models. We distinguish a visually persuasive explanation from one that faithfully describes the model’s behavior.
Explainable Transformer Prototypes investigates learned representative image patterns and the relationships between them. A new image can be compared with these prototypes, making aspects of the model’s evidence more inspectable. The research includes quantitative and qualitative evaluation; a highlighted region or prototype match alone does not establish clinical reliability.
Exposing and evaluating image evidence
- Learn representative image patterns or identify regions associated with a prediction.
- Present relationships between the input and those learned representations.
- Evaluate explanations as well as the predictive model they describe.
Selected research sources
Research enquiries
Contact the lab